Governing Dual-Use AI Risks in Biology with the Life Sciences Verification Program
The Life Sciences Verification Program gives verified organizations recalibrated AI safety filters to safely accelerate critical biological research.
Copy, download or open this article in ChatGPT or Claude
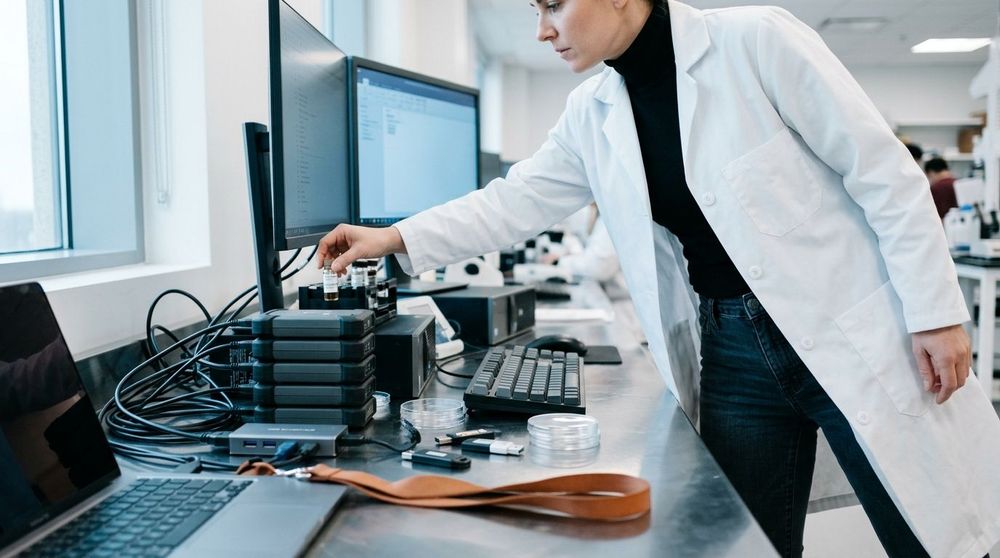
AI is transforming structural biology and drug discovery. But the same tools that help map proteins can also be used to design dangerous pathogens or toxins. To mitigate this risk, AI developers typically use safety filters to block chemistry and biology queries. The problem is that these blunt safety protocols often block harmless, critical scientific research.
Now, a new beta program aims to solve this bottleneck. The Life Sciences Verification Program gives verified organizations recalibrated safety filters so critical research is no longer blocked when using models like Mythos, Opus, and Sonnet. It is an effort to keep scientific progress moving forward without compromising on safety.
A Tiered Framework for Verified Research
The program is not open to everyone. It is restricted to life science teams of all kinds, such as academic labs, biotech startups, and pharmaceutical companies. To get access, applicants must prove their scientific credentials, show they have secure digital infrastructure, and demonstrate internal ethical oversight. Once approved, they receive a Standard Use grant, with the option to apply for a High-Risk Use add-on:
1. Standard Use Grant
This grant is built for a wide range of tasks, from basic science and R&D to manufacturing, supply chains, clinical development, quality control, regulatory reviews, and investment research. Managed at the team level, standard grants are valid for one year before needing renewal. It gives teams access to Mythos 5.1, Opus 5, and Sonnet 5 with adjusted filter settings. Essentially, it dials down the false positives so researchers can work without constant, unnecessary interruptions.
2. High-Risk Use Add-on
This add-on targets highly sensitive projects that would normally trigger complete safety blocks, such as modeling immunogenic responses to viral vectors. Unlike the standard grant, these add-ons are project-specific and expire after six months. Under this option, standard biological safety filters are turned off entirely for the approved project. High-Risk access currently supports Claude Opus 5 and Claude Sonnet 5. Access to Claude Mythos at this level is limited to a small group of organizations with extra vetting at launch, and Anthropic is working with the U.S. government to expand this in the future.
Security Architecture and Data Protection
To balance safety with usability, the program shifts from real-time prompt blocking to retrospective, offline telemetry analysis. Instead of stopping researchers mid-workflow, the system reviews usage patterns after the fact. The security design is built to protect against three key threats: hacked accounts, threats from insiders, and misuse by autonomous AI agents.
Several key protocols keep this system secure:
- Telemetry Retention: Interaction data is stored for 30 days to check for behavioral red flags or potential evasion techniques.
- Data Isolation: This telemetry is kept separate from standard datasets. It is never used to train models and is off-limits to Anthropic's life sciences research teams to protect proprietary research.
- Shared Responsibility: Organizations must declare exactly what they plan to use the AI for, and the system monitors usage to ensure it stays within that plan. If the monitoring flags suspicious activity, it alerts the organization's system administrators, who must take action within pre-agreed timeframes.
- Persistent Defenses: Only biological safety filters are modified. Standard protections against cyberattacks and other non-biological risks remain fully active.
However, this shared responsibility comes with a real operational cost for customers. Most academic labs and small biotech startups do not have a dedicated team that can receive an alert about potential misuse and quickly investigate it. Because of this, we will likely see the rise of a new AI operations function designed to handle these alerts, much like security teams handle cybersecurity events today. Similarly, having a clearly declared AI use case will likely become a standard compliance document, similar to how companies handle data privacy assessments.
Right now, the beta is limited to organizations using developer APIs, Claude for Enterprise, or Team plans. It is not available for individual accounts or on third-party platforms.
Ultimately, this program is less about biology and more about a new way of managing safety rules. Instead of blocking every single request, it relies on knowing who the user is, having them declare what they are working on, and checking their usage afterward. This is very similar to how large companies govern privileged access to their most critical systems today. The key signal in this setup is that it explicitly treats autonomous AI agents as a threat to guard against. While checking logs after the fact means that misuse is only caught after it happens, filters that judge each prompt on its own cannot see misuse spread across multiple sessions—which is exactly what offline pattern monitoring is designed to catch. The real trade-off here is detection speed against detection coverage, rather than safety against convenience. This style of verified access will likely spread to other sensitive areas, like cybersecurity research. Eventually, organizations will need to declare exactly how they plan to use AI and agree to set response times to get access to the most advanced models.
There is also a major question about how this program will work in Europe. As launched, the program is very US-focused. It involves the US government in approving certain access, relies on US healthcare-specific legal rules (meaning it is not available for organizations with special US privacy agreements), runs only on the developer's own systems, and requires keeping all research prompts for 30 days. It remains to be seen whether European drug companies, including the major biotech hub in Belgium, will accept this data retention under their strict data-privacy policies. Furthermore, nobody is sure yet how this requirement to declare a specific use case will fit with the complex rules of the European Union's AI Act.
Related articles
Microsoft Drafts a Humanist Code of Conduct for Future Models
Microsoft unveils its Humanist AI Code of Conduct draft, setting ethical & safety rules for future AI, prioritizing human welfare & preventing misuse.
Measuring AI Capabilities with Precision Using Item Response Theory
BenchMIRT leverages psychometrics for precise AI evaluation, analyzing individual prompts for capability, safety, and bias, cutting costs and improving transparency.
Hallucination is not a hygiene problem
The first advocate-general at Belgium's Court of Cassation devoted this year's opening address to AI, and to the tools the judiciary does not have.