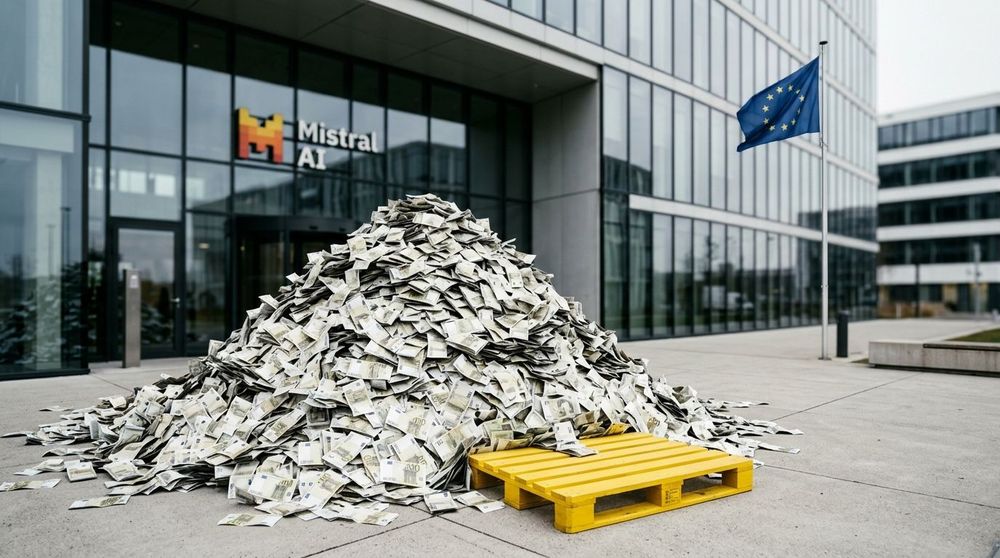
Mistral.AI's €3 Billion Deal
Sovereign AI: Enterprises host private, secure AI models, eliminating public cloud data risks & boosting independence. Mistral AI is a key player.
Copy, download or open this article in ChatGPT or Claude
Integrating commercial artificial intelligence models into enterprise workflows presents a persistent security headache. The standard approach depends heavily on public clouds. This means companies have to route proprietary code, sensitive user telemetry, and internal business logic through external API endpoints, introducing real data exposure risks and tying critical processes to the uptime of third-party vendors.
To bypass these vulnerabilities, many enterprises are shifting to a sovereign AI architecture. In this setup, companies host open-weight models inside their own isolated private networks, removing the need to send data payloads to third-party environments entirely.
Sovereign AI System Architecture
In a sovereign AI deployment, all data and telemetry remain strictly within the corporate network perimeter. Here is how that pipeline contrasts with standard public cloud routing:
Public Cloud Pipeline:
[User Input] ---> [Public Internet] ---> [Outside Cloud Server] ---> [External Output]

Sovereign Pipeline:
[User Input] ---> [Local API Endpoint] ---> [Private GPU Server] ---> [Secure Output]
Successfully implementing this self-hosted pattern relies on four technical pillars:
- Localized Storage: Databases, vector indexes, and embeddings are kept entirely within the private network boundary.
- Weight Ownership: Software developers run execution engines from private code repositories, allowing them to manage weights and fine-tuning parameters directly.
- Private Compute: Dedicated physical GPUs and virtual machine instances run in on-premises facilities or isolated, private cloud data centers.
- Total Audibility: Security teams retain full access to inspect and monitor every single execution pathway in the active pipeline.
By moving to a self-hosted stack, enterprises gain complete independence from third-party API pricing changes and unpredictable external outages.
Commercial Scaling and Capital Allocation
Building the tooling for this localized approach has become a highly lucrative market. Mistral AI, the French enterprise software firm, has emerged as a major player here, developing the core frameworks, open-weight models, and client utilities required for local setups.
The company recently secured €3 billion in Series D funding at a valuation of more than €21 billion, marking one of the largest venture rounds in European technology history. This is a massive step up from the company's €1.7 billion valuation during its Series C round, which was led by ASML a year earlier.
Samsung Electronics led this latest Series D round. Other major participants included PSG Equity and the EQT-managed Scaleup Europe Fund. New investors like Advent, funds managed by BlackRock, and the Luxembourg government also joined the investor roster alongside existing backers:
- Andreessen Horowitz
- ASML
- Belfius
- BNP Paribas CIB
- Bpifrance
- Carmignac
- DST Global
- Eurazeo
- General Catalyst
- Headline
- Hillspire
- Index Ventures
- Korelya Capital
- Lightspeed
- Nvidia
- Phoenix Court's Solar fund
- Salesforce Ventures
Mistral AI plans to use this capital to scale its physical compute footprint and train its next generation of models. The company currently supports over 125 enterprise clients, including Airbus, ASML, and HSBC, across 20 countries. Its leadership team has set a target of €1 billion in annual recurring revenue (ARR) by the end of 2026.
While Mistral AI is scaling rapidly in Europe, it operates alongside massive US-based competitors. For context, OpenAI closed a funding round with $122 billion in committed capital in March 2026, valuing the company at $852 billion. Even with those figures, European businesses are actively seeking regional alternatives to avoid total lock-in with US platforms. This caution was highlighted in June 2026 when the US government briefly implemented export controls on US-based Anthropic, demonstrating the practical risks of relying on overseas infrastructure.
Production Case Study: Self-Hosted Telecom and Fab Operations
These sovereign setups are already running in high-stakes environments. Samsung Electronics is currently integrating Mistral Large inside its semiconductor fabrication plants, hosting the model on its own private hardware.
The local implementation functions as a straightforward three-stage pipeline:
- Ingestion: The system gathers raw machine data and manufacturing logs straight from the plant floor.
- Routing: This telemetry routes directly to a local Mistral Large endpoint on a private server.
- Analysis: The model analyzes the logs to spot microchip anomalies, optimize tools, and boost overall manufacturing speed.
Running this workflow locally keeps highly confidential silicon designs completely off the public internet.
To give developers even greater control over these pipelines, Mistral AI rolled out updates in August 2026 that let enterprises pinpoint the exact physical data zones where their queries are processed. On top of that, the platform now supports hosting third-party open-weight models, including foundational models engineered in China. This allows enterprise engineering groups to manage multiple model vendors within a single, private orchestration framework.
While hosting model weights locally is an important step, the surrounding architecture matters just as much. This includes document searching, user logins, safety logs, backups, and tracking tools. Companies need to show where their data goes, who can see it, and if their main work can keep running if an outside provider goes offline.
Simply running models locally does not completely guarantee safety. An AI model inside a company network might still leak private files to staff who should not see them, or do things it should not do when linked to other tools. For safety, apps must control who can access what. In fact, standard security guides on prompt injection suggest limiting what the AI is allowed to do and requiring real humans to approve risky actions.
Understanding 'open weights' also requires caution. Just because a company has access to these weights does not mean they own them, can use them for any commercial project, or fully understand how the model behaves. For example, Mistral uses different rules and licenses for different models.
To make sure a system is truly independent, sovereignty should be something a company can actually test. This means checking exactly where models are running, restricting network access, managing file permissions, keeping track of model versions, practicing recovery plans, and proving they can switch to another model provider if needed.
The costs also need careful planning. Running models locally means the company itself has to handle server space, keep systems online, update software, and manage daily operations. When comparing choices, businesses should look at the actual cost of finishing a task, along with their goals for quality and safety backups.
In the future, many businesses will likely use a mix of methods. They might use local models for highly private or critical tasks, and use approved cloud services where they make sense. The best setups will make these choices clear and make it easy to move work between different systems.
Ultimately, the real test of independence is whether an organization can run, inspect, recover, and change its AI systems entirely on its own terms.
Related articles
Building Time-Series Pipelines with IBM Granite PatchTST and TinyTimeMixers
IBM Granite offers open-source PatchTST & TinyTimeMixers for scalable time-series forecasting. Pre-trained AI for enterprise & edge deployments.
Microsoft Launches MAI-Image-2.6 and MAI-Image-2.6-Flash
Microsoft launches MAI-Image-2.6 & Flash models. Top-tier image generation with advanced editing, web grounding & speed. Great quality & cost-effective.
Google Launches Lyria 3.5 for Multimodal Music Generation in Gemini
Google launches Lyria 3.5, an AI model for high-fidelity music generation with multimodal input, natural vocals, and detailed control, available in Gemini.